Models Retrained By Hand
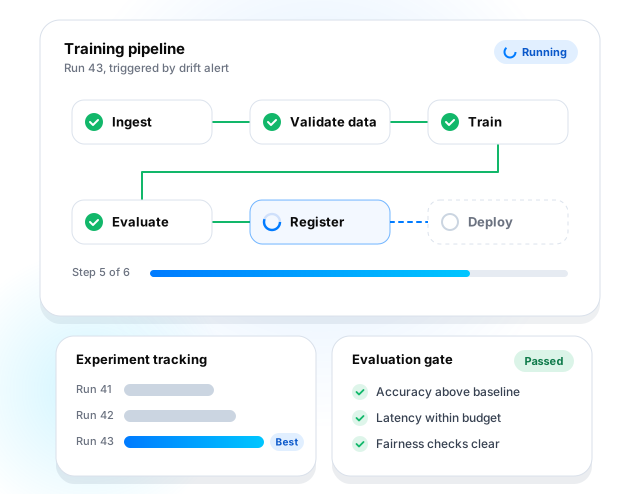
Retraining still means one person rerunning a notebook. When that person is away, the model goes stale. A versioned training pipeline removes the dependency.
Fix: Training Pipeline
Machine Learning Operations
Build repeatable machine-learning delivery pipelines for training, testing, deployment, monitoring, rollback and model lifecycle management.
We engineer ML CI/CD, model registries, feature stores, release paths and production monitoring on the cloud and ML platforms you already run.
Proven AI Delivery
Our 400+ AI specialists are part of SDLC Corp's 1,200+ engineering team. Together, they have completed 300+ AI deployments and 120+ enterprise AI integrations.
Trusted by Fortune Global 500 leaders, governments & top universities across 30+ countries


Powered by leading cloud & AI platforms
Awards & industry recognition


What We Build
MLOps (machine learning operations) takes models from experiment to reliable production. SDLC Corp builds and runs the pipelines, registries, feature stores, release paths and monitoring that let every model be rebuilt, released and rolled back.
Every model release tested on code, data and behaviour before it ships.
Batch and online serving with gradual releases and a tested rollback.
One system of record for versions, approvals and where each model runs.
Every training run logged, so any result can be compared and reproduced.
One definition per feature, shared by training and live predictions.
Drift and quality alerts, plus the telemetry that explains them.
Explore all 6 MLOps services
Readiness
Most teams reach for MLOps when models start to outgrow manual handling. These six signs show where that happens, and each one maps to the MLOps maturity levels described by Google Cloud.
Retraining still means one person rerunning a notebook. When that person is away, the model goes stale. A versioned training pipeline removes the dependency.
Fix: Training Pipeline
The code, data and settings behind it were never recorded, so nobody can reproduce or explain it. Experiment tracking keeps that record for every run.
Fix: Experiment Tracking
Deployment is a manual handover, so releases queue behind whoever knows the steps. ML CI/CD turns it into a tested, repeatable release.
Fix: ML CI/CD
Quality drops quietly, and customers notice before your team does. Instead, model monitoring tracks drift and alerts a named owner first.
Fix: Model Monitoring
Each model computes its own inputs with slightly different logic. As a result, training and serving drift apart. A feature store defines each feature once.
Fix: Feature Store
When someone asks who approved a model and what data trained it, the answer should take minutes. A model registry records approvals, lineage and where each version runs.
Fix: Model Registry
Delivery
Software pipelines test code. ML pipelines also test data and model behaviour, then release each model gradually with a tested way back. Our guide to ML CI/CD and model deployment pipelines covers each gate in detail.
Unit tests for feature logic, schema and volume checks on training data, and fixture tests for edge cases. The training pipeline itself is versioned and tested, so it can produce an equivalent model on demand.
Holdout performance, comparison with the current model, segment metrics and serving constraints such as latency and payload size.
One immutable model package moves through every environment. Code commit, data snapshot, feature versions, environment and seed are recorded, so any version can be rebuilt and explained.
Scheduled scoring for forecasts and reports, or low-latency API endpoints sized for peak traffic and measured against a latency budget.
A candidate first scores live traffic in shadow mode. Next, it takes a small canary share with guardrails. Finally, traffic switches over while the previous model stays warm.
The previous model, its features and its schema stay servable, and the switch back is rehearsed. So reverting a release is routine, not an emergency.
Lifecycle Control
Together, model registry and experiment tracking record how every candidate was made and which ones are trusted. Meanwhile, a feature store keeps training and live inputs the same.
Tracking And Registry
Parameters, metrics, datasets and artifacts logged with hashes for every run, including failed ones. As a result, new candidates are judged against a real baseline.
Immutable versions linked to the run, code and data that produced them, with evaluation reports, model cards and lineage attached.
Lifecycle states from candidate to production to archived, with the approver, date and evidence recorded on each version.
Which version serves where, since when, and what it replaced, so rollback is a lookup.
Feature Store
Each feature defined once with an owner. A production feature store then serves it from an offline store for training and an online store for low-latency predictions.
Training rows use only values available at prediction time, and parity checks catch training-serving skew. However, batch-only or single-team models may not need a feature store at all.
Operations
Model monitoring in production shows when a model's decisions change. Continuous training then retrains it on a pipeline, with the same gates as the first release.
Live inputs compared with training data per feature and segment. Shifts in scores often show up before labelled outcomes arrive.
Accuracy and business metrics compared with the approved baseline. Thresholds are set per model, and alerts go to a named owner with a runbook.
Requests traced from gateway to model server with one correlation ID, and latency tracked per stage. With this enterprise AI observability in place, an incident ties back to the change that caused it.
Drift, measured degradation, new labelled data or a known business change, each with a defined response.
A fixed cadence for models such as forecasts, or retraining started by monitoring signals once the training data itself passes validation.
Retrained candidates face the same gates as any new model. In addition, high-impact models keep a named approver, in line with the accountability roles in the NIST AI Risk Management Framework.
Architecture
A reference flow for production ML. Each stage leaves a record the next can rely on, and the supporting layers keep every stage traceable.
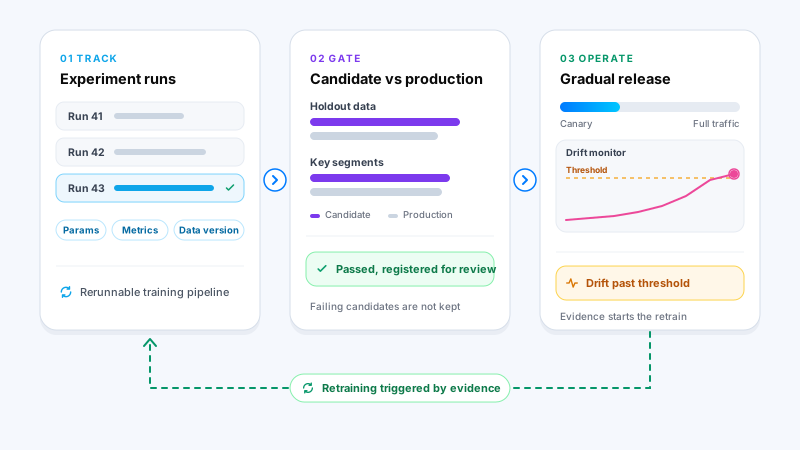
Experiments and training runs log parameters, metrics and data versions, and training is a pipeline that can be rerun rather than a notebook session.
Candidates are compared with the production model on holdout data and important segments, and only those that pass are registered for review.
Releases expose a model gradually, monitoring watches quality and drift, and retraining is triggered by evidence rather than habit.
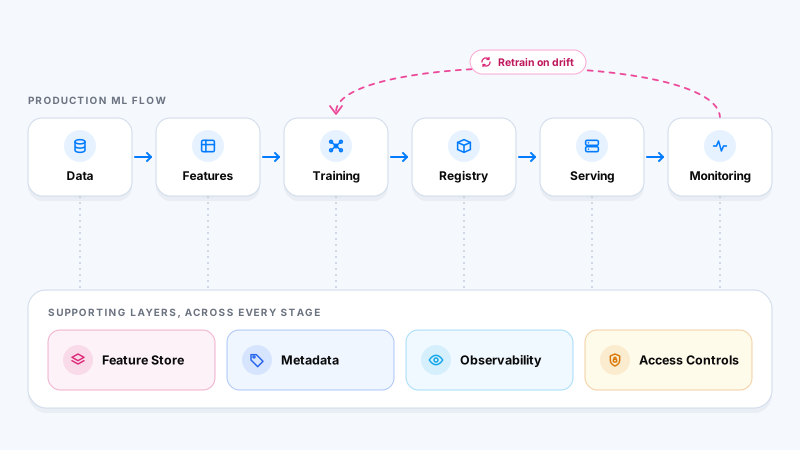
Consistent features for training and serving.
Runs, versions, lineage and approvals in one record.
Telemetry across every stage and dependency.
Who can train, approve, deploy and read data.
Tech Stack
Each stack starts from the cloud you already use. We pair a managed ML platform, such as Amazon SageMaker, Vertex AI or Azure Machine Learning, with Kubernetes and NVIDIA GPUs for training and serving. Models are built in PyTorch or TensorFlow, and open models from Hugging Face, Llama or Mistral run through the same pipelines. That way, your team can run and extend it without us.
In Practice
Lifecycle practices from published SDLC Corp engagements, described as delivered. Each one shows what it takes to move AI pilots into production and keep them reliable.
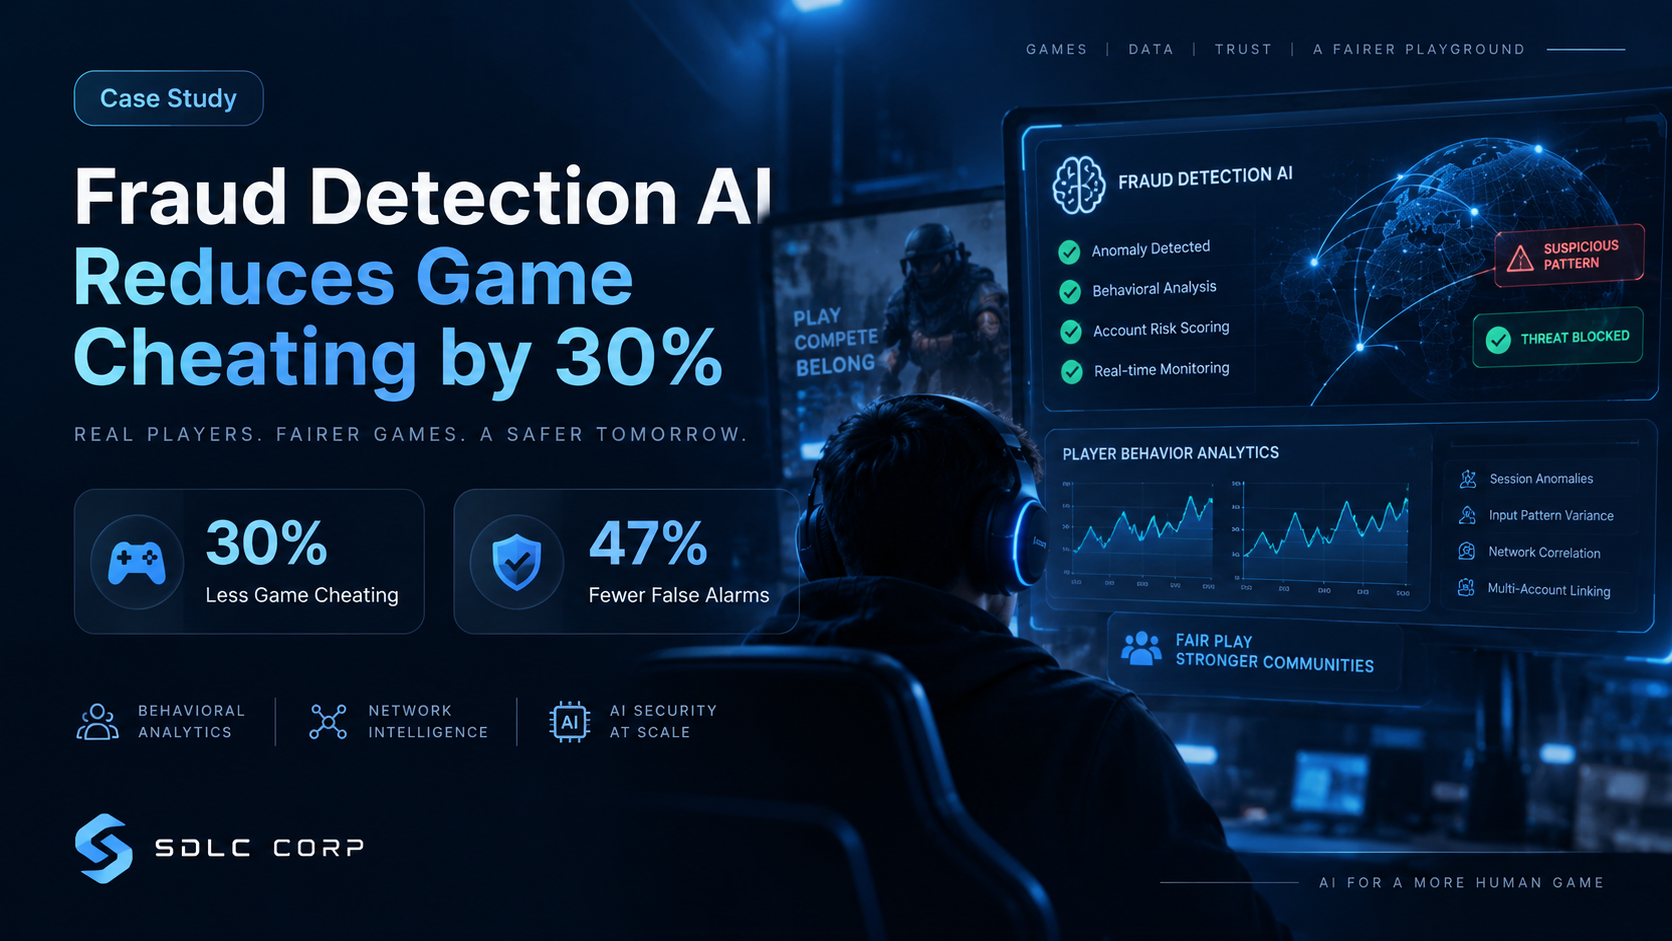
View More AI Case StudiesWhat We DidGraph models run on a live event stream from an on-premise Kubernetes GPU cluster. Each release went through a shadow-mode phase before full deployment. An offline retraining pipeline then refreshes and redeploys the model from disputes and recent play data.
ResultIn-game cheating cut by 30%.
Lifecycle Controls
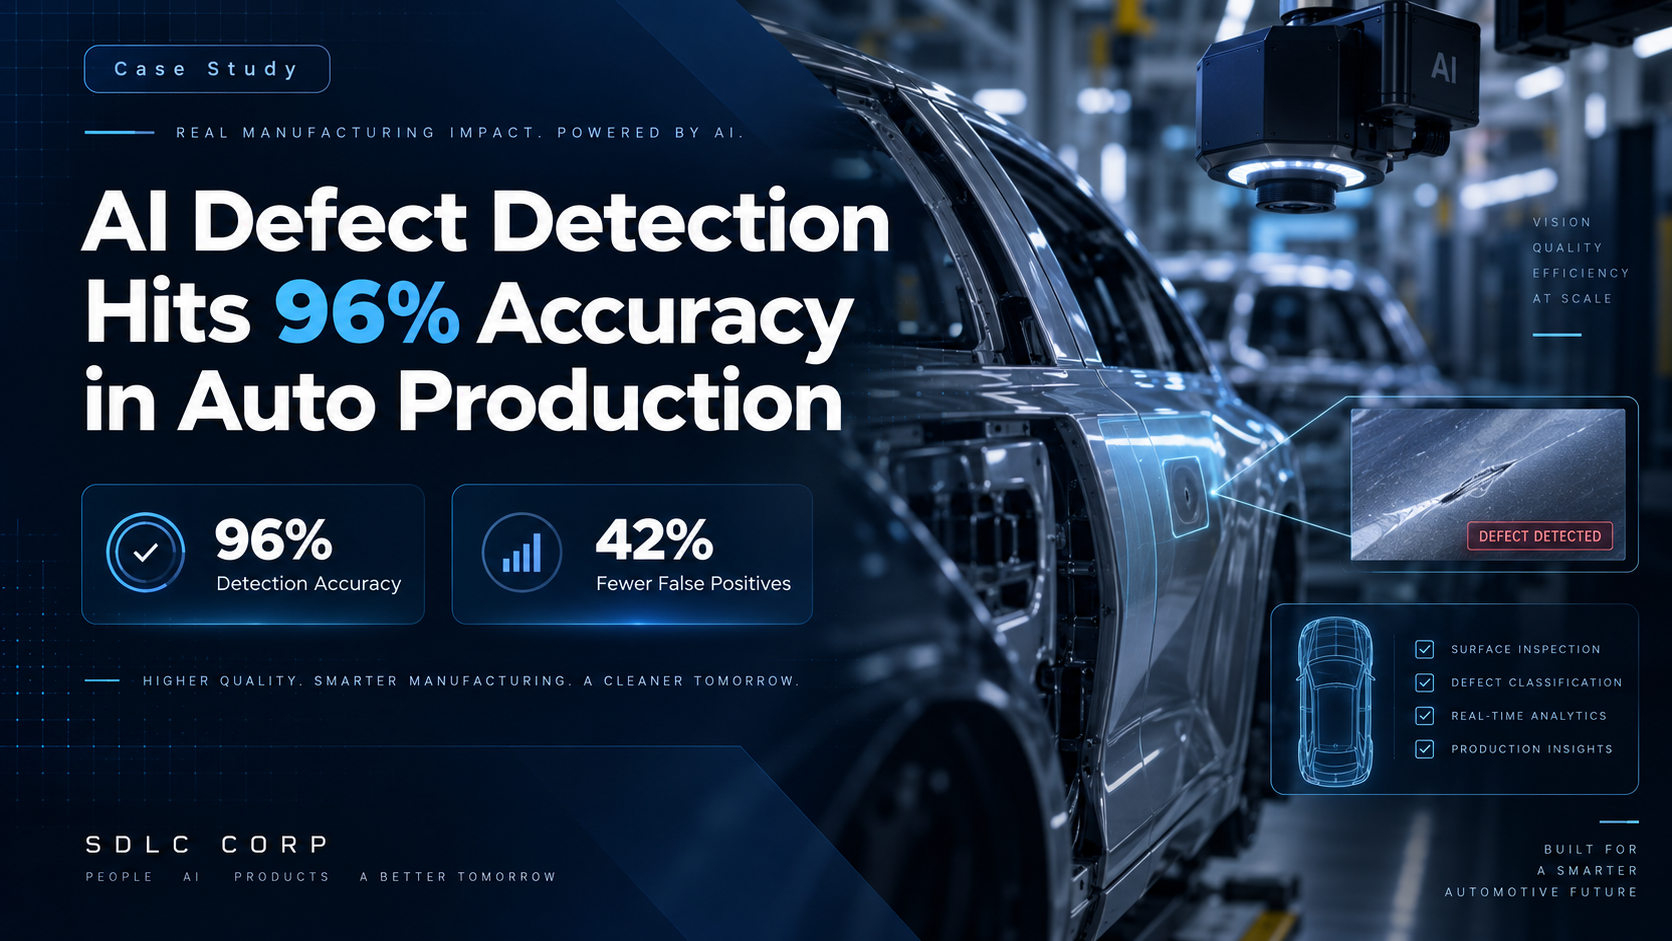
What We DidWe compiled a vision model for edge inference beside the paint line. Each week, plant technicians trained in the procedure retrain it on site with newly flagged frames, so it absorbs lighting and colour drift.
ResultDefect detection accuracy rose from 81% to 96%.
Lifecycle Controls
What We DidAn AI workflow sends exceptions to a person for approval. Approved corrections and confirmed mappings are kept and reused. As a result, the system improves from validated outcomes rather than unreviewed output.
ResultInvoice-to-OTM shipment-cost handling where every correction is traceable to an approved decision.
Lifecycle Controls
How We Work
Four ways to work with us, from a first assessment to running the platform for you. Each stage has a measure we track, so progress is visible.
MLOps consulting starts here. We review how your models are trained, released and monitored today, and where lineage, gates or rollback are missing. Then we agree ownership for each model risk tier.
You Receive
Maturity report and roadmap.
Measured By
Share of models with full lineage and a named owner.
We build training pipelines, experiment tracking, registry integration and packaging on your platform. As a result, every run is recorded and every candidate can be rebuilt.
You Receive
Working pipeline, registry and runbook.
Measured By
Share of models that can be rebuilt from the registry.
Next, we add promotion gates and shadow, canary or blue-green release paths with rollback rehearsed. Drift and system alerts then go live with named owners.
You Receive
First models live with rehearsed rollback.
Measured By
Deployment frequency and rollback time.
We put monitoring, rollback and named owners in place before you scale, not after the first incident. Then we either run the platform for you or train your team to run it.
You Receive
Monitored models, managed releases and current runbooks.
Measured By
Drift alert response time.
Get Started
Operationalize Machine Learning
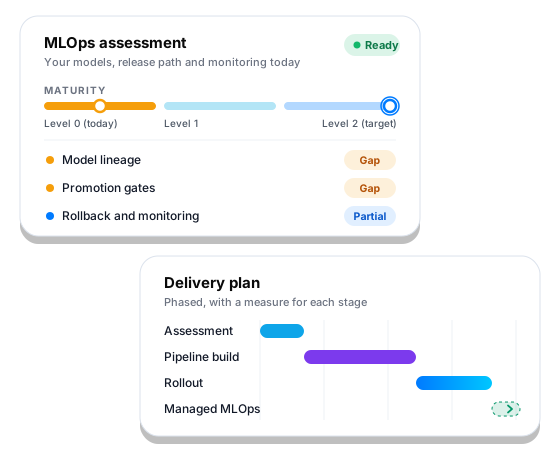
Build repeatable pipelines for training, deployment, monitoring and model lifecycle management. Tell us which models you run, where they are deployed and how they are released today, and we will come back with an assessment and a delivery plan.
FAQ
Straight answers on ML pipelines, registries, feature stores, deployment, monitoring and how MLOps compares with DevOps and LLMOps.
MLOps services design, build and operate the lifecycle infrastructure behind production machine learning: CI/CD for models, registries, feature stores, release paths, monitoring and retraining workflows. The goal is that any model can be rebuilt, released, monitored and rolled back through a repeatable process rather than individual effort.
Cost depends on how many models you run, how many platforms they span, and how much is already in place. A focused assessment costs far less than a full pipeline, registry and monitoring build. Managed operation is usually priced monthly. After the assessment, we give you a fixed estimate for each phase, so you can approve one step at a time.
An assessment usually takes 2 to 4 weeks. Building pipelines and a registry for the first models takes 6 to 10 weeks, and a production rollout with monitoring and rehearsed rollback takes 4 to 8 weeks. Timelines grow with the number of models, data sources and approval steps. Existing tooling on SageMaker, Vertex AI or Databricks often shortens the build.
Build in-house if you already have platform engineers with ML experience and time to spare. A provider makes sense when models are waiting to reach production, or when your team lacks pipeline, registry and monitoring experience. A common middle path is to have a provider build the foundation while your team learns to own it.
MLOps is the set of engineering practices that move machine learning models from experimentation into reliable production and keep them reliable afterwards. It covers training pipelines, experiment tracking, model registries, feature management, deployment, monitoring and retraining, applied consistently across every model.
DevOps automates how code is built, tested and released. MLOps applies the same ideas to machine learning, but adds data and models. A model can fail while its code stays the same, because the live data changes. So MLOps also versions datasets, validates model quality before release, tracks drift in production and retrains models when performance drops.
MLOps focuses on the lifecycle of trained models and the data behind them. LLMOps extends that lifecycle to prompts, retrieval indexes, model routing, evaluation of open-ended output and dependencies on external model providers.
Google Cloud describes three levels. At level 0, data scientists train and deploy models by hand. Level 1 automates the training pipeline, so models retrain on new data without manual steps. Level 2 adds CI/CD for the pipeline itself, so teams can test and release pipeline changes quickly. An MLOps assessment shows which level you are at and what the next step needs.
Yes. We build on the platform you already use instead of moving you to a new one. That includes managed ML services on AWS, Azure and Google Cloud, Databricks, and open-source stacks on Kubernetes. Pipelines, registries and monitoring are designed around your platform's native services first.
Yes. Under managed MLOps, we watch drift and system alerts, run retraining and releases, and keep runbooks current. Alternatively, we train your engineers to run the platform themselves and stay on call for escalations. Many clients start with managed operation and then hand over once their team is ready.